You Need a Real AI Computer
1,326 Views
Keep Your Private Files on Your Computer
The more you need AI to help you think something through, the more you have to tell it. Say you’re trying to reply to a difficult email. To write a decent reply, the AI needs to know what the other person promised, what’s changed, and what you’ve already told them. Send the whole thread to an AI in the cloud and the company running it gets all of that, too.
You know which email could hurt you if it got out or which document gives away something private about someone else. To a company processing files all day, the one you’d keep under lock and key is just another attachment. It could leave a copy on a server or pass through another company’s systems. Someone could get the permissions wrong. The system could get hacked. Someone with access could use the file for their own purposes. It only takes one of those things for a file to end up where you never meant it to go.
You were just thinking out loud. Pull one sentence from the chat and somebody can make it sound like you were laying out a plan. If the file gets out, the company can fix the system and send a notice. You’re the one who has to explain what you said. It’s happened before. The ChatGPT story · The Claude story
If there’s even one detail you wouldn’t want made public, keep it off cloud AI APIs. This is why it matters to have a computer of your own that can run AI. You can give it the whole email thread, let it draft a reply based on what actually happened, and keep both the thread and the draft on your computer.
The model understands the email and writes the reply. Another piece of software, called a harness, opens the files you choose, gives them to the model, and saves the draft wherever you tell it to. Together they make an agent that can do the job. Run both on your computer and give the agent access only to the files it needs.
Your AI Shouldn’t Refuse to Help You
Say you’ve written a post and want the agent to put it in your browser, where you can review it before it goes out. If the agent won’t even paste the draft, you’re back to finding the page and pasting the text yourself. You handed it the job precisely so you wouldn’t have to do those steps.
Ask an AI to post through your own browser, place an order on Robinhood, or analyze a network problem. Any of those requests can get blocked. The same job can go through on one computer and get stopped on another. Sometimes it’s the commercial model that blocks you. Sometimes it’s the software around it, like Codex.
Taking over once is fine. It’s having to wonder where the agent will stop next time that makes it hard to rely on. Say it’s drafted an email. You’ve checked the recipient and the text and said, “Go ahead and send it.” At the last step, it says it can’t. So you open your email, find the draft, and hit Send yourself. It’s your account and you approved the message. You shouldn’t have to tiptoe around the AI’s feelings just to send it.
On your computer, you can choose a community-made Abliterated model. People in the community have modified its weights so it will keep talking about some subjects other versions cut short. You decide which files it gets and which tools it can use. If a post is ready to go out, you still get the final say.
Your AI Shouldn’t Be Dumbed Down or Slowed Down
Yesterday you gave your AI an order spreadsheet and a shipping spreadsheet. It matched them and told you which orders hadn’t shipped. Today you’re scheduling the afternoon’s shipments. You give it the same two sheets and ask exactly the same question. Now it can’t even tell which columns go together. The work you handed off yesterday is back on your desk.
Some providers send a share of requests to a new version to see how it does. They can also change where those requests go and how the model runs. If your request lands in the test, you’re the guinea pig. The screen still shows the same model name. That name tells you very little about what actually ran. You planned today’s work around yesterday’s results. Now the warehouse is waiting for the afternoon shipping list and you’re scrambling to fix step one.
Even a correct answer can come too late. When there’s a shortage of compute in the cloud, API requests can pile up. The GPT API has slowed down before when the compute available to it dropped. The warehouse still needs its list. The agent has to match the spreadsheets, figure out what hasn’t shipped, and then make the list. Each step waits for the last one to finish. The warehouse is waiting on you, and you’re waiting on a progress bar.
Keep the model and its settings on your own machine and you can use the same version tomorrow. How fast it runs comes down to your computer. A cloud provider can’t swap out the model you saved or turn down the speed on your machine.
How Much of Your API Bill Goes to Compute?
You pay for the API, wait for a response, and get a refusal. So you try asking another way. Then you try again. You’re the paying customer. Why are you the one who has to beg?
In October 2026, DeepSeek shared some numbers on how it runs V4.1 Flash. A single cluster handles 155 trillion tokens a day. At off-peak API prices, that works out to $38 in revenue per GPU per hour. For the sake of argument, say the GPU costs $6.50 an hour. Take out that one cost and you’re left with $31.50, about 83% of the implied revenue. You’d need the full cost of running the service to get the actual gross margin. DeepSeek’s deployment Q&A
Here’s what providers were charging per million output tokens in November 2026. DeepSeek V4 Pro was $3.96 at peak hours. At standard rates, Claude Opus 5.5 was $20 and GPT-6 Astra was $50. That’s about five and thirteen times DeepSeek’s price. Now take $3.96 as a separate example and suppose 83% is left after paying for the GPU. That’s about $0.67 in GPU costs per million output tokens. Double that for a bigger model and you’re still looking at about $1.35, or 6.7% of a $20 price and 2.7% of a $50 price. Under those assumptions, a doubling of GPU costs comes nowhere close to explaining the difference.
Anthropic gives us a look at the whole company. It reported $33.242 billion in revenue for the first nine months of 2026 and $4.812 billion in cost of revenue. Almost all of that cost was for the compute and infrastructure used to serve customers. Do the math and the company-wide gross margin is around 85.5%.
Some people are good enough at what they do to command high pay. Since when are salaries and company valuations this high a given? Some of these companies charge you a premium and make hefty margins, then sit in judgment over what you’re allowed to ask.
You’ve paid and you still have to ask them to let the question through. Want a stronger model? You get it if they feel like giving it to you. They can slow you down or send your request to a weaker one. They’re bleeding you dry. The company controls the compute, collects the rent, and still tells you how to do your work. How is that any different from a landowner squeezing his tenant farmers?
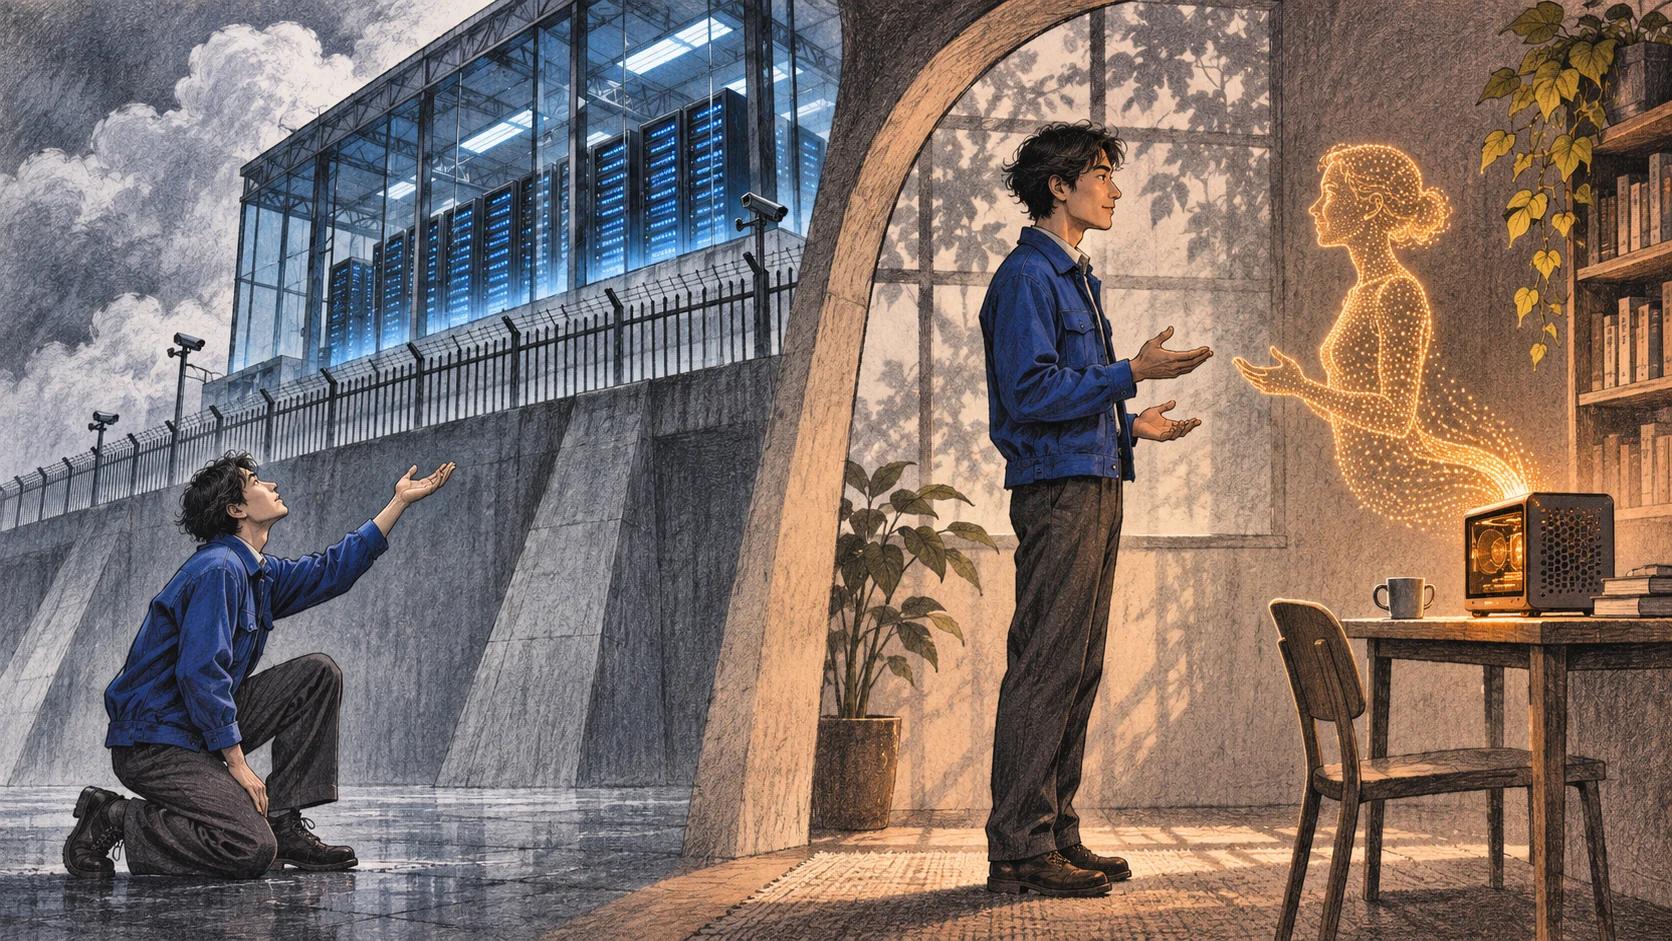
Keep a Little Plot of Your Own
When you rent a place, you have to ask about renewing the lease. Buy it and you decide how long to stay. With a rental car, you have to see what’s available. With your own car, you can get in and go. Buying a computer that runs AI locally works the same way. It costs more up front than renting cloud AI. What you get for the money is a choice you can make for yourself every day. Which model do you want to use? When do you need it?
The cloud can have the biggest, prettiest farm in the world. What does that do for you? This little plot is yours. Plant what you want, when you want.
Two Very Different Computers
Put two computers side by side and either will do fine for writing a document. Try running the large model you want to use. One runs out of memory and has to hand the job to the cloud. The other can run the model right there on your desk. You can give it the original files and it can do the job where those files already live. For you, these are two entirely different machines.
See what you can run on the computer you have. If you’re shopping for a new one, look for an Apple Silicon Mac with plenty of unified memory or a Windows or Linux machine with an NVIDIA RTX card. On that second route, consider the GPU memory, the computer’s memory, and SSD space together. Two public Mac tests give you an idea of what to expect.
- Qwen3.8-27B (27 billion parameters, 4-bit quantization). On a 64 GB M5 Pro, oMLX with DFlash acceleration used about 19–23 GB at peak during inference and generated about 21–33 tokens per second. If you’re buying a Mac for this model, I’d start at 48 GB of unified memory.
- Qwen3.8-Flash-Next (125 billion parameters in the main model). With Strata, the IQ2_XS version needs an estimated 42 GiB, so you can try it on a 64 GB Mac you already have. A 96 GB M2 Max produced about 25–29 tokens per second in testing. A 128 GB M5 Max can run IQ3_S. In Strata’s story-writing test, that configuration generated 74.3 tokens per second, or 94.1 with MTP acceleration turned on.
What does that cost? In the U.S. in November 2026, a MacBook Air for everyday use was roughly $1,000 to $2,000. The 16-inch MacBook Pro that can run Flash-Next IQ3_S, with an M5 Max, 128 GB of memory, and a 2 TB SSD, was about $6,400, in the $6,000 to $7,000 range. The desktop Mac Studio with an M5 Max, 128 GB of memory, and a 1 TB SSD was about $5,400. All prices are before tax.
How to Set It Up
You can ask Codex to install the official DeepSeek Harness desktop app, download a model, and pick software to run it, such as oMLX or Strata. The software runs the model on your computer and gives the harness a local address to connect to. Give Codex this prompt.
Install the official DeepSeek Harness desktop app. Download the latest compatible community Qwen Abliterated release for this computer. Install a compatible runtime, load the model, and start the local service. Point DeepSeek Harness at the configured localhost address and select the model you just downloaded. Give the harness its own working folder, restrict its file access to that folder, and turn off cloud sync for the folder.
Open DeepSeek Harness and make sure your new local model is selected. Ask it something simple. Once it answers, you can start using it. Before you give it the private files for a job, check who can access the working folder and make sure it’s set to stay off cloud sync.
I hope you find an assistant you can really trust, right there on your own computer.
1,326 Views
New ideas, straight to your inbox.
AI, engineering, and experiments. One or two useful emails a month.
No spam. Unsubscribe anytime.