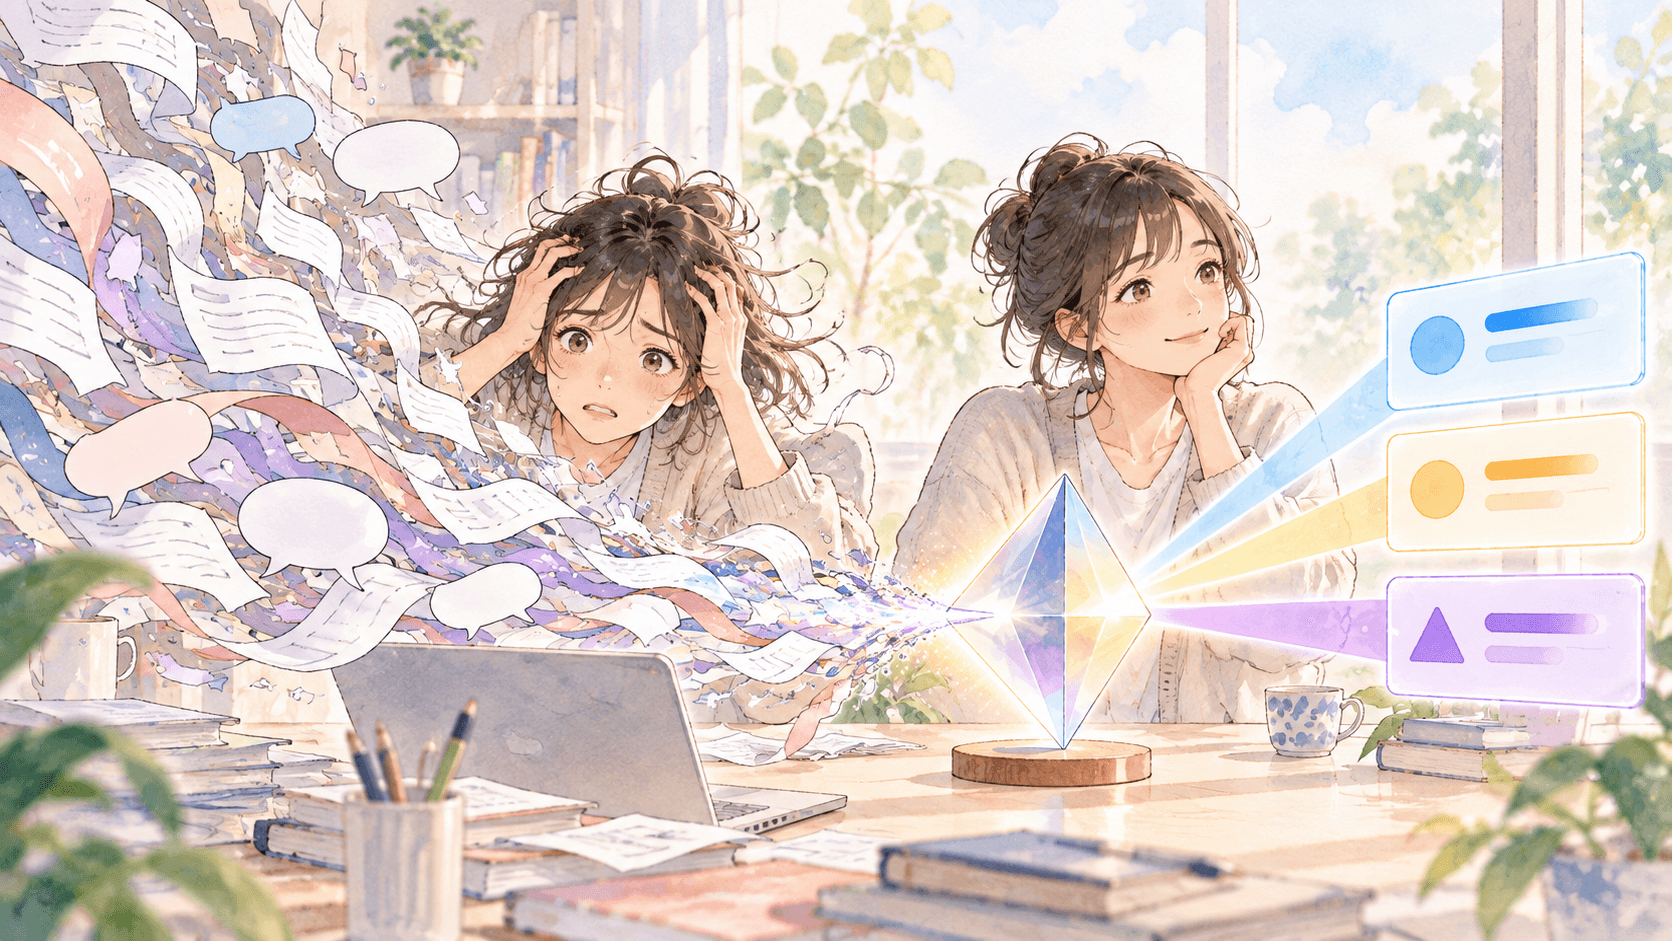
Jev: Probabilistic Decisions in Hundreds of Milliseconds, Without Text Generation
Ask a person a question they cannot answer and they can say, “I don't know.” Ask a large language model and it will often begin with, “That's an interesting question.” From there, things can get complicated. An LLM is a little like someone unexpectedly called on by the boss in a meeting: there may be only thirty percent confidence in the brain, but the mouth has already announced point one, point two, and point three. By point three, whether point one was true is no longer the immediate problem; the immediate problem is avoiding an awkward silence.
The model is not deliberately lying. Its job is to keep writing: look at the existing text, predict the next token, then use that token to predict another. Until it produces an ending, it has to continue. A weak guess that enters the context becomes the premise for everything that follows. An imaginary company can quickly acquire a founder, a funding history, and a corporate culture. Apart from the company not existing, the profile may be impressively complete.
Today's language models are extremely capable, but their default output is still text. A person can read that text, doubt it, and ask a follow-up question. Software has a harder problem. It usually does not need “a thoughtful discussion.” It needs to know: is this A, B, or C; how certain is the answer; and when should the case go to a person instead?
TypeSafe AI's Jev starts from that question. It does not chat or write long answers; give it state and several explicit questions, and it returns choices, scores, and probabilities. Jev is not trying to become a model that can say everything. It is designed to make judgments inside software. That may sound like doing less, but in production systems, doing less is often how a product finally becomes usable.
Top-K and Top-P Control How a Model Talks, Not Whether It Should
Understanding Jev does not require advanced mathematics; think of an LLM as a next-word prediction machine. After “The capital of France is,” the model ranks possible next tokens, with “Paris” far ahead. When a question is obscure or the evidence is incomplete, the leading candidates may be much closer together. However uncertain the model is, the interface still asks it to choose one, and Top-K, Top-P, and temperature control how that choice is made.
Top-K keeps only the K most likely candidates. If K is 10, the top ten advance to the final round and everyone else gets to go home early. Top-P, or nucleus sampling, does not choose a fixed number. It starts with the most likely candidates and keeps adding them until their combined probability reaches a threshold such as 90 percent. Temperature controls how adventurous the contest becomes: at a low temperature, the favorite almost always wins; at a high temperature, an underdog may get a trophy.
These settings affect whether the output is stable or creative. They do not determine whether an answer is true. Reducing Top-K from 50 to 5 narrows the words the model can select; it does not make missing evidence appear. Setting temperature to zero chooses the most likely next token each time, not a sentence guaranteed to be correct.
The reason is simple. The model estimates whether a token fits the preceding text, not whether the entire claim corresponds to reality. Once it invents a plausible company name, “Inc.” may become highly probable. Linguistically, everything is going well. The corporate registry may have a different opinion.
Hallucination is therefore not merely a sampling setting that needs adjustment. The deeper problem is that the model contains probabilities, but the application receives only finished text. Probability helps the model continue speaking instead of helping the program decide whether it should act. The natural engineering response is to constrain the output: instead of letting the model write an essay, make it fill out a form. That gave us JSON mode, Structured Outputs, and schemas. The LLM finally put on a suit and looked ready for production, but a guess wearing a suit is still a guess.
JSON Makes the Answer Tidy; Jev Makes It Actionable
Structured output is genuinely useful. If an application needs:
{ "department": "billing" }
that is safer than asking for three paragraphs of analysis and inferring from a polite conclusion that the model probably meant finance. A schema can guarantee required fields, correct types, and values drawn from a declared enum.
The ordinary LLM underneath is still generating one token at a time. JSON solves the format, not necessarily the judgment. The application knows the result is billing, but not whether the model selected it with 95 percent certainty or flipped a particularly well-read coin between billing and technical.
Real systems therefore often travel a longer path: write a prompt, generate JSON, validate fields, convert types, interpret confidence, and only then enter business logic. A program that merely wanted “A or B” has, through modern AI engineering, acquired a small supply chain. Jev places its interface at the end of that chain: it accepts state and questions, then returns the values the program was trying to obtain.
There are three basic question types. Choice selects from predefined answers and returns the probability of every option. Score rates the state along ordered levels and returns a distribution over them. Noul returns a number from 0 to 1 representing the probability that a statement is true.
Suppose a customer writes, “Stripe has failed for three days. We are losing orders. Please help now.” A normal LLM may generate an analysis. Jev can tell the application that the ticket has a 0.81 probability of belonging to technical support, a 0.99 probability of being urgent, and a 0.65 probability of representing high frustration. The program no longer has to interpret the model's tone: it can route the ticket to technical support, raise its priority, or send it to a person when the department probabilities are too close. The model understands ambiguous language, while code owns thresholds, authorization, and execution; neither has to moonlight in the other's job.
Jev's Real Value Is Giving Uncertainty to the Program
For a person, words such as “probably,” “appears,” and “I tend to think” can communicate uncertainty; for software, their main contribution is keeping regular expressions awake at night. Software needs a number. At a fraud probability of 0.97, a system might hold a transaction; at 0.68, it might request more verification; at 0.42, it might take no action. A model does not have to be correct every time, but the system must be able to behave differently when the model is uncertain.
This is why a probability can be more useful than a complete response. It can rank candidates, set automation thresholds, trigger human review, and later be compared with the actual outcome. A model mistake stops being an isolated “why did it say that?” incident and becomes data that can be measured and improved.
Want more practical breakdowns?
AI, engineering, and experiments. One or two useful emails a month.
No spam. Unsubscribe anytime.
TypeSafe calls Jev's training method Reinforcement Learning for Calibrated Decisions, or RLCD. The important word is calibrated. In plain language, if a model repeatedly assigns 80 percent probability to a group of predictions, roughly 80 percent should eventually prove correct. This does not guarantee any individual answer. It makes the probability meaningful across many decisions. One naming trap is worth avoiding: TypeSafe's RLCD is not the 2023 paper Reinforcement Learning from Contrast Distillation. They merely share an acronym.
Public information about how Jev is actually trained remains sparse. TypeSafe has disclosed three layers: a new model architecture, a sampler that produces several outputs in parallel, and RLCD training aimed at calibrated decisions. It has not published the network design, model size, training data, reward function, loss, weights, or a reproducible training recipe. Any more specific story—for example, that Jev is distilled from an LLM or uses a particular classification head—would currently be inference rather than fact.
For Choice and Score, Jev returns the complete probability distribution and a confidence statistic derived from how concentrated that distribution is. Noul returns the probability of the proposition directly. Applications still need their own historical data to test whether thresholds work in their domain. A shoe store and a bank blocking wire transfers should not take the same action simply because both saw 0.8.
TypeSafe also says Jev cannot hallucinate, and the precise meaning is structural. If the declared departments are billing, technical, sales, and other, Jev cannot invent a Quantum Customer Happiness department; if the contract requires a number, it cannot return a poem. It may still choose the wrong available answer, but the error remains inside a space the program defined in advance. That is not “the model can never be wrong.” It is a way to put model errors inside a manageable enclosure, which is already meaningful progress for production software.
How Jev Is Used
The integration is conceptually simple: place the customer message, account state, or document in state, then list the judgments the program needs. The following is pseudocode rather than the exact syntax of one SDK, because the shape of the interaction matters more than the imports:
result = Jev.evaluate(
  state = customer_message,
  questions = {
    department: choose billing / technical / sales / other,
    urgent: return a probability from 0 to 1,
    frustration: score from calm to angry
  }
)

if department confidence is below 60%: send to a person
if urgent and technical: notify the on-call engineer
otherwise: route by department and frustration
The real Python SDK expresses these questions with Choice, Noul, and Score objects. The important part is not the function names. One business state produces several judgments that can enter program control directly, without generating an explanation first and then asking the application to recover what the model intended.
Each question should make one judgment. “What should we do about this customer?” is too broad and resembles asking the model to run the entire company for the afternoon. It is better to ask separately whether the customer requested a refund, which department owns the issue, how severe the impact is, and whether the available evidence is sufficient. Code can combine the results.
This design also explains Jev's speed and cost advantage. A conventional LLM processes the input and then writes the answer token by token. Jev operates within an answer space defined in advance, and multiple questions can run in parallel. TypeSafe reports end-to-end latency of roughly 70 to 500 milliseconds, input pricing of $0.042 per million tokens, and no separate charge for output. Actual numbers will vary by workload, but the direction is straightforward: if the program needs a judgment, there is little reason to pay the model to write an essay and then pay engineers to turn the essay back into a judgment.
Can a Prompt Turn an LLM into Jev?
The short answer is that an LLM can imitate Jev's interface without becoming Jev. TypeSafe's own open-source System One Adapter demonstrates this directly: an ordinary LLM combined with prompting, JSON Schema, and Structured Outputs can return Choice, Score, Noul, and a probability for every option. The two systems can look nearly identical to an application while taking very different computational paths. Giving an essayist a multiple-choice answer sheet does not turn the writer into a grading machine.
The first difference is what the probability means. When an LLM is asked, “How confident are you?”, its 0.9 is still a generated string, and the model may sound equally confident when it is right and wrong. A stronger design constrains the labels, derives a distribution from their logits, and then applies temperature scaling or isotonic calibration on held-out outcomes. Many APIs do not expose stable, comparable label logits, however, and multi-token labels introduce further bias. JSON can guarantee that 0.9 is a number. It cannot guarantee that the number deserves to be 0.9.
The second difference is the computation path. After reading the input, an LLM still generates the opening brace, field names, choices, probabilities, and closing brace sequentially. More questions produce more JSON and more waiting. Jev claims to share one state and evaluate every independent question in parallel. In one official example, batching 13 questions into a single request was 9.6 times faster than making 13 separate calls. The questions did not become easier; parallel fan-out removed repeated state processing and serial round trips.
How large is the overall gap? In TypeSafe's workflow evaluation averaged across four business processes, Jev reached 67.8 percent accuracy in 0.4 seconds. The Terra workflow reached 67.9 percent in 10.1 seconds, roughly 25 times slower. The Sonnet 5 workflow also reached 67.8 percent but took 78.1 seconds, roughly 195 times slower. That explains the company's “up to 193.6x faster” headline while showing why it is not a universal constant. TypeSafe acknowledges that these workflows are near the high end of expected gains; its team designed the evaluation, and the reference answers come from a consensus of large models. This is a company benchmark with inspectable data, not an independent result.
A tiny local classifier may beat a remote Jev call on a fixed binary task, and a fast non-reasoning LLM returning one label can narrow the gap considerably. Jev's strongest case is not that it is the fastest classifier in existence. It is that questions and choices can be defined at runtime, require near-frontier semantic understanding, and still produce a dozen judgments in a few hundred milliseconds. The useful metric is intelligence per second, not merely tokens per second.
Could a team train something similar? For a stable domain with fixed labels, yes. Collect business state, questions, and actual outcomes; use a strong model plus human review to bootstrap labels; then train a small encoder, cross-encoder, or language model with a classification head. Noul becomes binary probability, Choice a softmax over candidates, and Score an ordinal classification problem. Optimize proper scoring objectives such as cross-entropy or Brier score, calibrate on a separate validation set, and track accuracy, Brier score, expected calibration error, and P95 latency. Most companies do not need to recreate Jev; they need to train the one decision they repeat a million times.
The hard part is allowing new questions and new answer spaces at runtime. Today's options may be support departments, tomorrow's may be browser buttons, and the next day's may be 200 tools. A fixed classifier cannot handle that. Approaching Jev requires an instruction-conditioned scoring model that encodes the shared state once, understands each question and candidate in natural language, and emits calibrated logits for all of them in parallel. Keeping that system open-ended, accurate, fast, and calibrated is precisely the part TypeSafe has not disclosed—and likely the technical moat. A prompt can reproduce the surface. It cannot reproduce the training and inference pipeline underneath it.
It Will Not Replace the LLM, but It May Sit Beside It
The most direct applications are support routing, document classification, refund-intent detection, lead scoring, security-alert triage, and search ranking. These tasks process language, but their final output is usually an option, a score, or a probability.
Agent supervision may be even more valuable. An agent run can contain a plan, tool calls, retrieved evidence, and a proposed action. Jev can separately judge whether the evidence supports the conclusion, whether the agent followed the user's constraints, whether the action is reversible, whether the response exposes sensitive data, and whether a person should review the run. The system receives enforceable signals rather than asking a second LLM to write an essay titled “Why the First LLM Could Have Done Better.”
Document workflows fit the same pattern. An invoice does not require literary merit. The system needs to know whether the vendor matches the purchase order, whether the amount is anomalous, whether delivery evidence is complete, and whether a discrepancy crosses a review threshold. Jev interprets; code does the arithmetic. This is usually safer than asking one model to serve as accountant, approver, and essayist.
In the two days after launch, several experiments on X began to make the idea concrete. Browser Use developer Gregor Zunic built an open-source browser agent that treats the current DOM as state and the available page elements as choices. At every step, Jev selects the next action; a small LLM is used only when text must be entered. In the demo, the agent searched Google Flights from Zurich to London in about seven seconds at a reported cost of $0.0039. Clicking through a website is not poetry. It is a sequence of multiple-choice questions, which makes it an unusually natural job for Jev.
Developer Paolo Rosson showed a different pattern. He supplied a pull-request diff once, then evaluated 14 questions in parallel, including checks for hard-coded secrets and SQL risks, with a probability returned for each. He reported a response time of roughly half a second and a cost of about $0.00007 per PR. The interesting part is not simply that “AI can review code.” It is that one shared input can produce a typed set of independent, probabilistic judgments. Code review does not always need another essay; sometimes fourteen warning lights are more useful.
The product surface is moving quickly as well. On September 16, Vercel announced that Jev was available through AI Gateway. AI SDK 7 exposes typesafe-ai/jev through its experimental evaluate API, returning several judgments and probabilities directly to an application. Jev is therefore no longer only an idea in a launch post; developers can place it inside existing gateway, logging, budget, and data-retention controls. The speed and cost figures above remain early developer-reported demos rather than independent benchmarks. Even so, they reveal something more important: once the interface changes from “generate text” to “return decisions,” the surrounding software architecture starts changing immediately.
Future AI systems will use more than one kind of model. Reasoning models will investigate, plan, explain, and generate. Decision models such as Jev will classify, score, verify, and route. Ordinary code will calculate, constrain, and execute. People will handle ambiguous cases with serious consequences.
Jev is still in early access. Public information does not yet reveal enough to evaluate the complete RLCD training method, and calibration across different businesses needs to be tested with real data. Those open questions do not weaken the central design. The direction is practical: instead of generating language first and searching it for a hidden decision, return the available decisions, their probabilities, and a signal that tells the system when to stop and ask for help.
The value of an LLM remains open-ended reasoning and generation. Jev's value is the recognition that not every request for intelligence should produce a small essay. Sometimes the complete answer a production system needs is the probability of A, the probability of B, and whether this is a good time to let the AI decide on its own.
References
- TypeSafe AI, Introducing System One Models & Jev, September 15, 2026.
- TypeSafe AI Documentation, Introduction and AI Primer.
- TypeSafe AI Documentation, Primitives, Confidence, and Quick Start.
- TypeSafe AI, Workflow Evals.
- Vercel, TypeSafe AI's Jev now available on AI Gateway, September 16, 2026.
- Gregor Zunic, Browser Use + Jev open-source browser-agent demo, September 17, 2026.
- Paolo Rosson, Jev pull-request review demo, September 17, 2026.
- TypeSafe AI, System One Adapter and Workflow Evals.
- TypeSafe AI Documentation, Ask multiple questions together and Confidence.
- Yang et al., RLCD: Reinforcement Learning from Contrast Distillation, 2023. This paper is unrelated to TypeSafe's training method of the same acronym.
The interpretations in this essay are the author's. Jev was in early access when this article was written on September 17, 2026; availability, API behavior, limits, latency, and pricing may change.
New ideas, straight to your inbox.
AI, engineering, and experiments. One or two useful emails a month.
No spam. Unsubscribe anytime.